← Blog
How to Tell Whether Your AI Assistant Is Actually Good
Summary
- Fluent answers are not proof of quality; measure the assistant on questions whose answers you already know.
- Build a test set of 50–150 real questions, including hard cases and questions the documents cannot answer.
- Measure retrieval, correctness, faithfulness, citations and refusals — plus response time and cost per answer.
- Group failures by cause, re-run the test set after every change, and set the quality bar by what a wrong answer costs.
Most AI assistants are approved on a feeling. Someone tries ten questions in a meeting, the answers look fluent, and the project moves on. Weeks later users report wrong answers, and nobody can say whether the assistant got worse or was never as good as it looked.
Fluent is not the same as correct. Language models produce confident text whether or not it is true, so the only reliable way to know how good an assistant is — and whether a change made it better — is to measure it on questions you already know the answers to.
Build a test set from real questions
A test set is a list of questions with the answer you expect, and ideally the source the answer should come from. Take the questions from real use: support tickets, emails, search logs, or a morning with the people who answer them today. Questions you invent yourself are usually too easy.
Fifty to a hundred and fifty questions is enough to start. Include the hard cases on purpose: questions that need a table, questions whose answer depends on a date or a version, questions that combine two documents, and questions the documents cannot answer at all. The last group tells you whether the assistant knows when to say “I don’t know”.
Measure more than “correct”
For an assistant that answers from documents, check at least these: did search find the right passage; is the answer correct; does it stay faithful to the passage rather than adding things; does it cite the right source; does it refuse when it should. A wrong answer caused by bad search needs a different fix from one caused by the model.
Two practical numbers belong next to quality: how long an answer takes, and what each answer costs in model and hosting fees. An assistant that is accurate but takes twenty seconds, or costs more per answer than the person it helps, is not finished.
Who grades the answers
The best graders are the people who answer these questions today. They spot answers that are technically true but useless, and answers that are subtly wrong in ways an outsider would miss. Their time is limited, so use them to grade the first rounds and the difficult cases.
Automated grading — often another language model comparing each answer with the expected one — makes it cheap to re-run the whole set after every change. It is useful, but it makes its own mistakes, so check a sample of its grades by hand each time rather than trusting the score alone.
Read the failures, not just the score
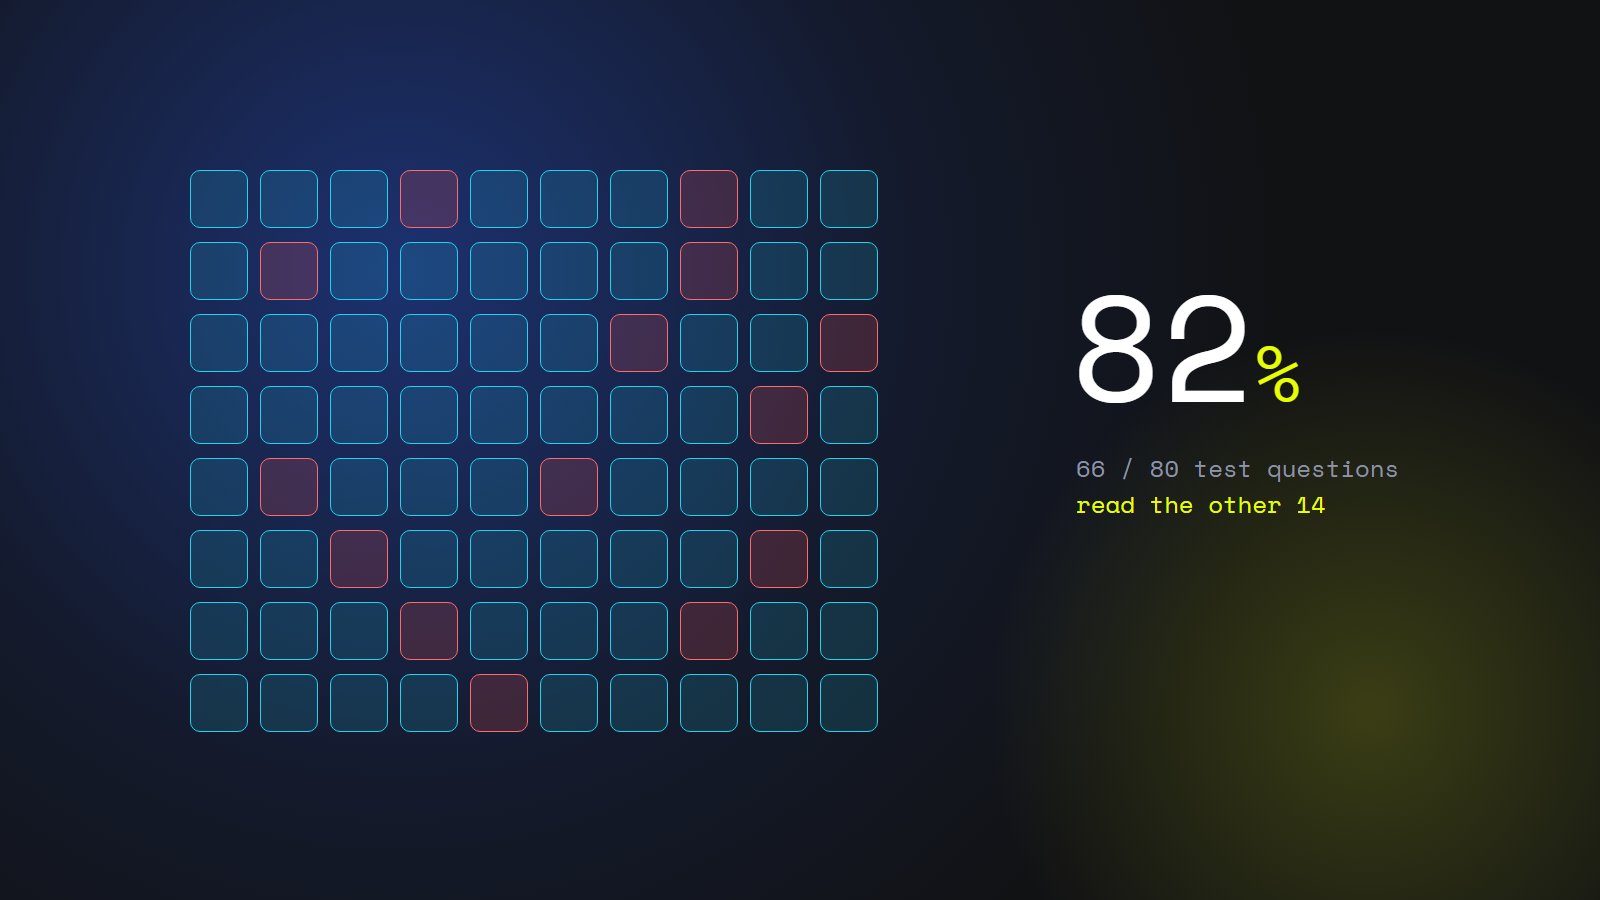
An overall score of 82% tells you little on its own. The value is in the 18%: group the failures by cause — the document was scanned and poorly read, the answer was in a table, two versions of a policy disagreed, the question was ambiguous — and each group points to a specific fix.
Some failures are not the assistant’s fault. Test sets regularly expose documents that contradict each other or answers that nobody wrote down. Fixing those improves the assistant and the business at the same time.
Keep measuring after launch
Quality drifts. Documents change, new products appear, users ask things nobody anticipated. Add a simple thumbs-up or thumbs-down to every answer, log the questions the assistant could not answer, and review both regularly.
Re-run the full test set every time something changes — a new model version, a new prompt, a new batch of documents — and add the real questions that failed in production. The test set grows into the most valuable asset of the project: proof of what the assistant can do.
What “good enough” means
There is no universal number. An assistant that drafts internal answers for a person to check can be useful at a lower accuracy than one that answers customers directly, and one that touches medical, legal or financial questions needs a much higher bar and a person in the loop.
Decide the bar before you build, based on what a wrong answer costs. Then the test set does the rest: it tells you when you have reached it, and when a change has taken you back below it.