Object detection & tracking
Finding, counting and following objects or people in images and live video.
Services
Projects
Blog
Our process
About us
 EN
 EN
AI & Machine Learning
Turning images and video into decisions.
From tumour segmentation on MRI scans to reading walls and doors off architectural drawings, we train vision models that do in milliseconds what takes a specialist minutes.
Computer vision lets software interpret images and video: find and count objects, outline regions, read text, spot defects, recognise products or flag anomalies in medical scans. Tasks that need a person to look at every image can be done in milliseconds, consistently, around the clock.
We have built vision systems for healthcare, where accuracy and explainability matter. We handle the full pipeline — collecting and labelling images, training and validating models, and deploying them where they need to run, whether that is a cloud API, a hospital server or a camera on the factory floor.
Computer Vision
Finding, counting and following objects or people in images and live video.
Pixel-level outlines of regions — tumours, defects, rooms on a floor plan, crops in a field.
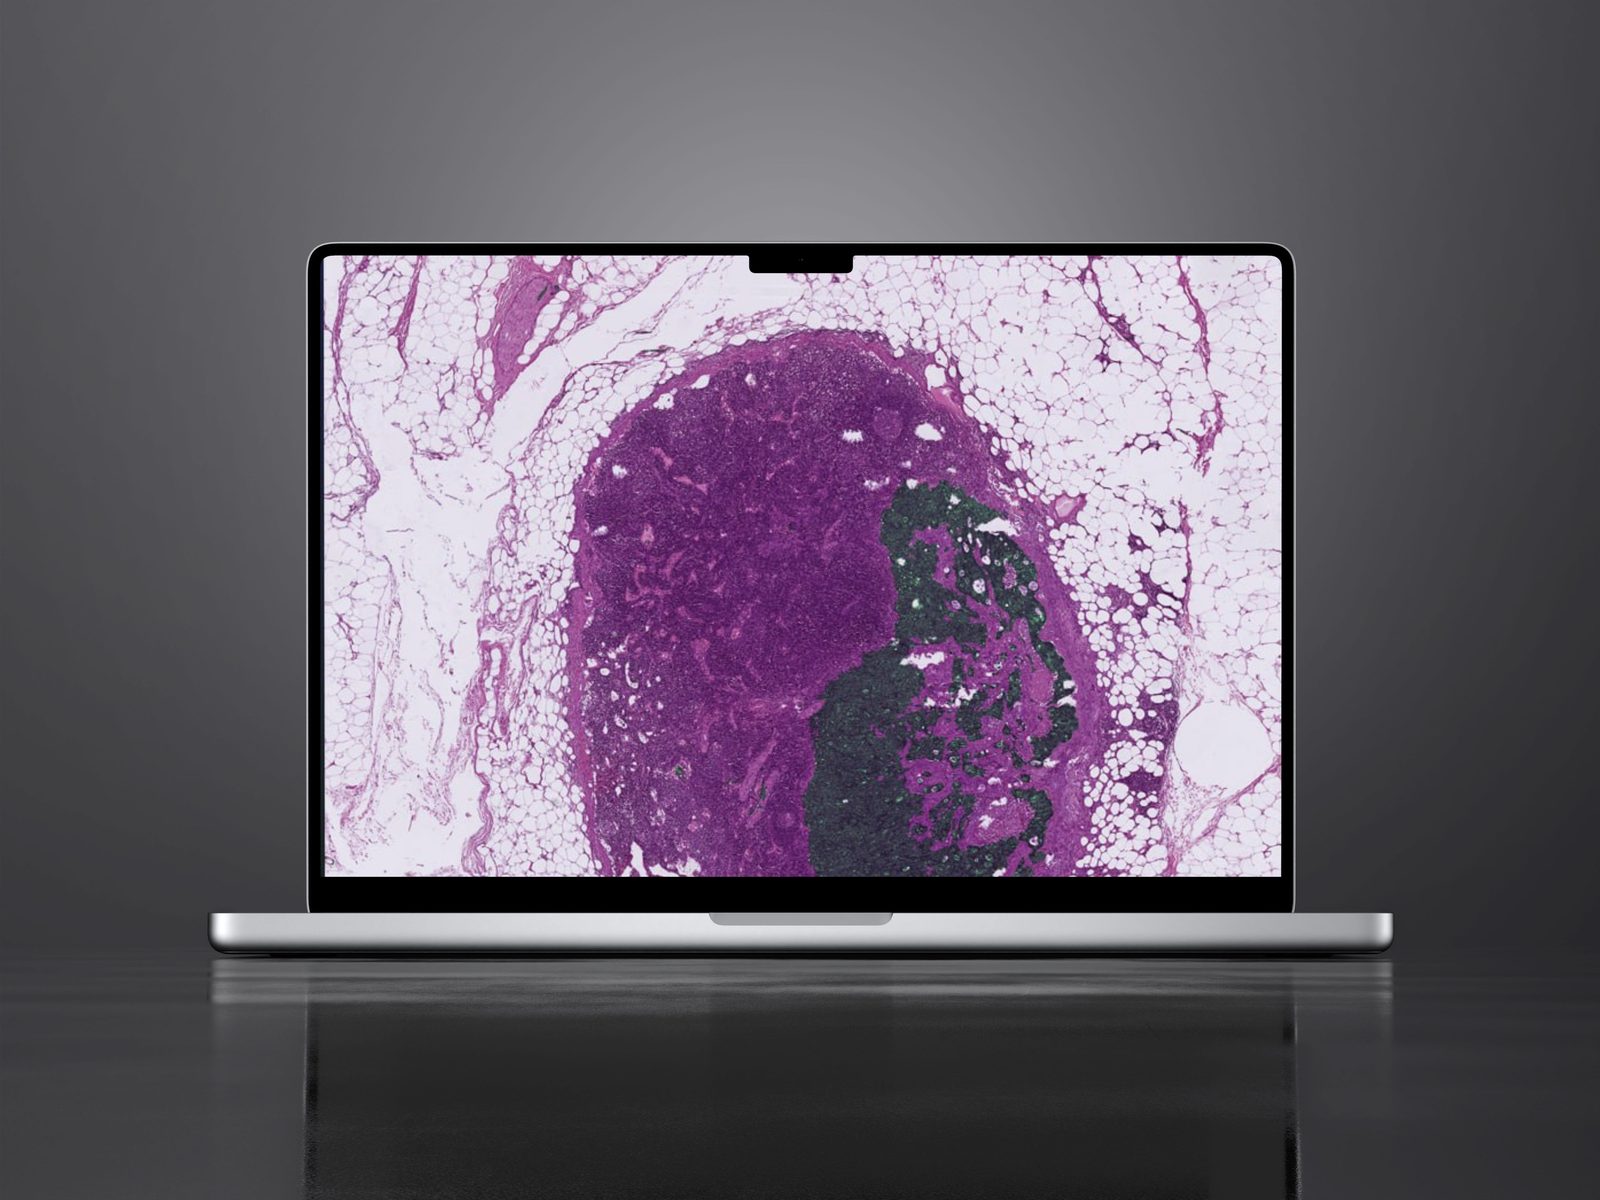
Models that assist with MRI, CT, X-ray and pathology images to help clinicians read scans faster.
Automated quality control that catches defects on production lines more consistently than manual checks.
Reading text, tables and handwriting from scans, photos, drawings and forms.
Optimised models that run on cameras, phones and on-premise devices without a cloud round trip.
Technology
Starting from pre-trained models, a few hundred to a few thousand labelled images per category is often enough for a first version. We assess your images early and can organise labelling if needed.
Yes. We optimise models to run on edge devices, on-premise servers or phones, so images never have to leave your site.
Yes — MedicMinder, our medical image analysis platform, works with MRI, CT and X-ray images. We handle medical data with strict access control and anonymisation.
Next step
A free 30-minute consultation with an engineer — no obligation, reply within one business day.
Contact usCookies, briefly
We use our own storage to remember your language and your choices. Third-party cookies come only from the chat widget and the booking calendar, and only if you allow them. Privacy & cookie policy